 Google Drive
 SharePoint
 Confluence
 Slack
 Jira
 GitHub
 Salesforce
 Zendesk
Research, not just retrieval
Agentic RAG plans its searches, reads across sources, and assembles a cited answer. Deep research mode turns hard questions into structured, multi-step reports.
KnowWiz is self-hosted AI chat and search connected to your docs, apps, and people. Cited answers from your own knowledge, running in your own infrastructure.
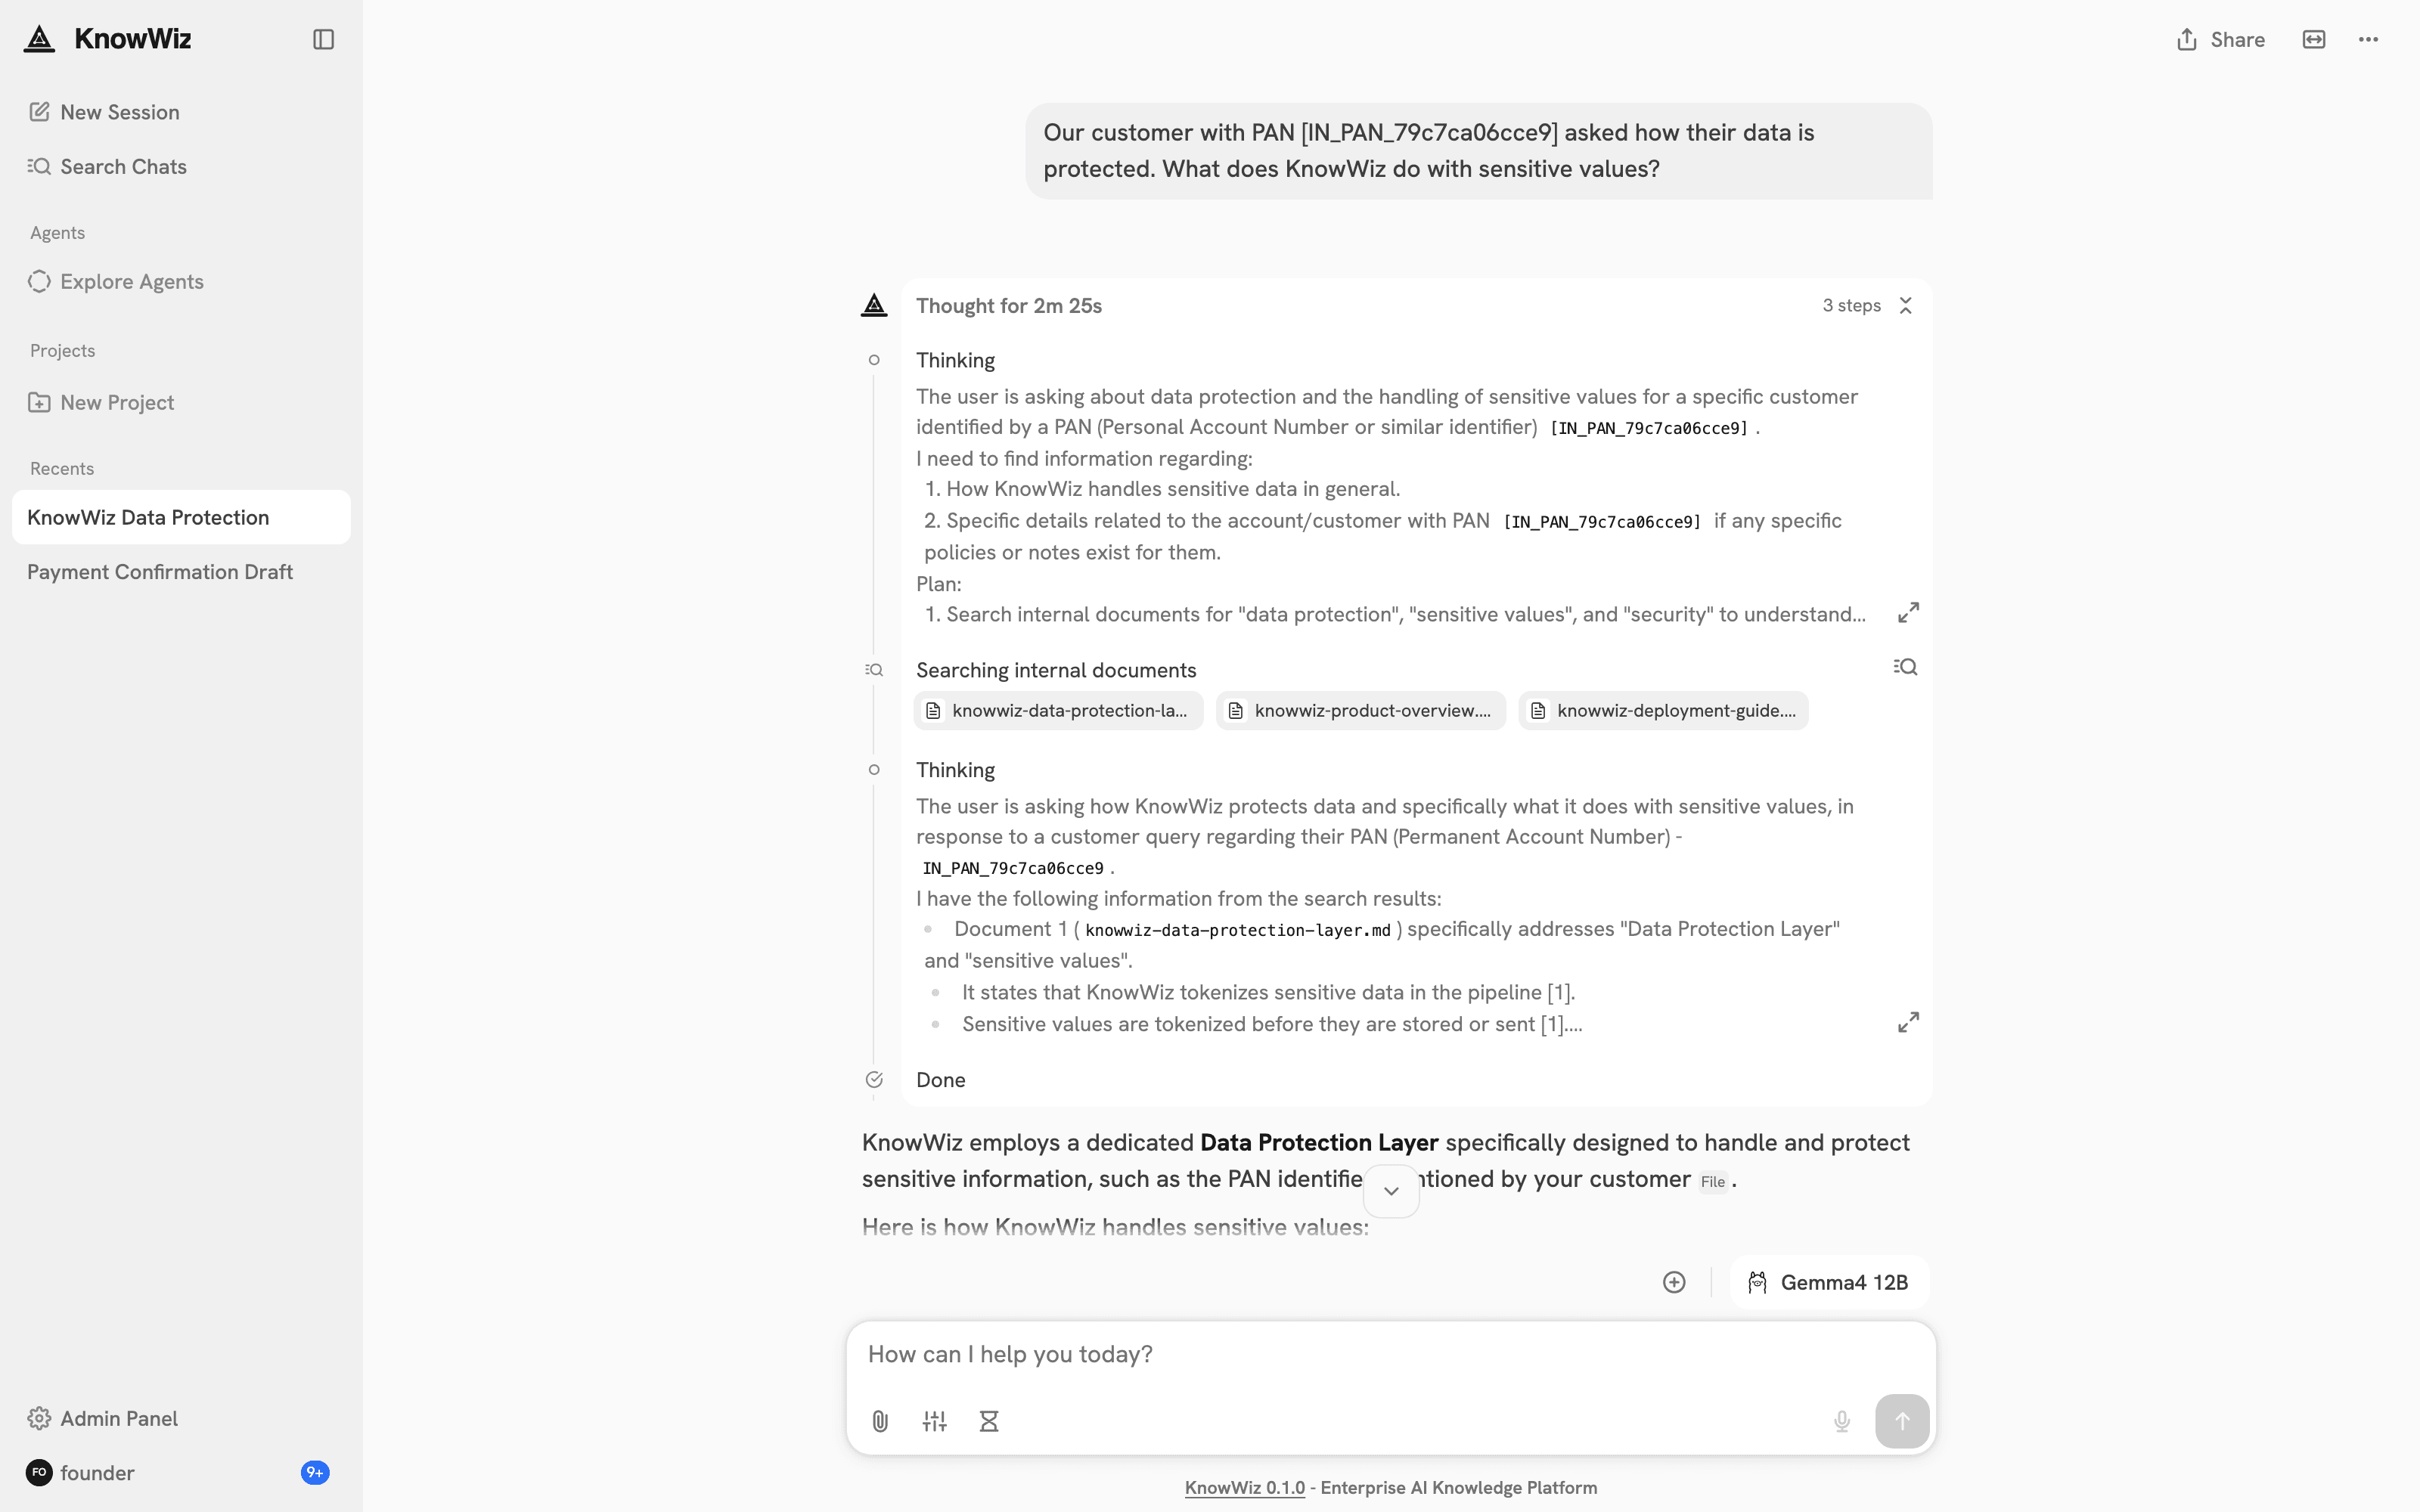
The question is typed with a real-looking PAN. By the time the model reasons about it, the trace shows only a token. Real product, real trace, and a cited answer at the end.
Searches across the tools your teams already use
The platform
Agentic RAG plans its searches, reads across sources, and assembles a cited answer. Deep research mode turns hard questions into structured, multi-step reports.
Custom agents with their own instructions, knowledge scope, and actions. Give each team an assistant that knows their corner of the company, and share what works.
Hybrid keyword and vector retrieval, grounded in your documents. Every answer links back to its sources, so a claim is one click from its evidence.
Anthropic, OpenAI, Gemini, or fully self-hosted through Ollama and vLLM. Swap providers without rebuilding your knowledge layer. Role-based controls throughout.
Why grounded
Knowledge lives across drives, wikis, tickets, and chat threads. People re-ask questions that were answered months ago, and public chatbots either don't know or make it up.
Sources. One search bar.
Wikis, drives, tickets, code, and chat, indexed into a single permission-aware layer.
Generic AI chat
Answers from nowhere
No access to internal knowledge, so it guesses. Answers are unverifiable, and every document pasted in leaves your control.
The KnowWiz approach
Grounded in your documents
Answers come from your own sources, with citations. Retrieval respects source permissions, and everything runs where you deploy it.
How KnowWiz works
Four steps from scattered documents to answers your teams can verify.
Point KnowWiz at the systems where work already happens. Connectors sync incrementally and pick up changes, additions, and deletions automatically.
Data protection
AI search only works if you can point it at your most useful documents, and those are exactly the ones with customer records, financials, and identifiers inside. KnowWiz can detect sensitive values and replace them with format-preserving tokens before anything is indexed or sent to a model.
Raw identifiers in the index or the prompt.
Detection and tokenization run inside your boundary, values keep their shape so search still works, and every masking action is recorded.
Typical RAG stack
Raw values everywhere
Documents go into the index as-is, prompts carry whatever the user pasted, and sensitive identifiers ride along to the model on every question.
KnowWiz
Tokens travel, values stay
Sensitive values, including regional identifiers like Aadhaar, PAN, IBAN, and national IDs, are tokenized at ingestion and on the prompt. The raw value never sits in the index or leaves for inference.
The user typed PAN ABCDE1234F. In the model's reasoning it appears only as the token IN_PAN_79c7ca06cce9, and the saved conversation keeps the token too, not the value.
Integrations
Connectors for your knowledge sources, sign-in against your identity provider, and models from any major provider or your own GPUs.
Google Drive
Documents
SharePoint
Documents
Confluence
Wiki
Notion
Wiki
Slack
Chat
Jira
Tickets
Zendesk
Support
GitHub
Code
Salesforce
CRM
Ollama
Self-hosted models
Use cases
Policies, processes, and institutional memory, answerable in one place. New hires stop interrupting and start finding.
Runbooks, design docs, incident history, and code context. The answer to "has anyone dealt with this before" in seconds, not a channel-wide ping.
Past proposals, deal context, and product answers pulled from the sources your team maintains, cited so reps can trust what they send.
Grounded answers drawn from tickets, docs, and internal notes. Agents resolve faster, and the answer trail shows exactly where each claim came from.
Connectors for the tools your teams already use
Self-hosted: index, models, and pipeline run in your infrastructure
Search bar across every connected source
Documents that leave your environment
See it on your own docs
A 30-minute working session: connect a source, watch the index build, and ask real questions against your own documents.
Self-hosted pilot on your infrastructure. Your data never touches ours.

